
' fill='%231A31FF'/%3E%3Cpath d='M148.667 101.667H148C142.399 101.667 139.599 101.667 137.46 100.577C135.578 99.618 134.049 98.0882 133.09 96.2066C132 94.0675 132 91.2672 132 85.6667V64.3333C132 58.7328 132 55.9326 133.09 53.7934C134.049 51.9118 135.578 50.382 137.46 49.4233C139.599 48.3333 142.399 48.3333 148 48.3333H148.667M148.667 101.667C148.667 105.349 151.651 108.333 155.333 108.333C159.015 108.333 162 105.349 162 101.667C162 97.9848 159.015 95 155.333 95C151.651 95 148.667 97.9848 148.667 101.667ZM148.667 48.3333C148.667 52.0152 151.651 55 155.333 55C159.015 55 162 52.0152 162 48.3333C162 44.6514 159.015 41.6667 155.333 41.6667C151.651 41.6667 148.667 44.6514 148.667 48.3333ZM115.333 75L148.667 75M115.333 75C115.333 78.6819 112.349 81.6667 108.667 81.6667C104.985 81.6667 102 78.6819 102 75C102 71.3181 104.985 68.3333 108.667 68.3333C112.349 68.3333 115.333 71.3181 115.333 75ZM148.667 75C148.667 78.6819 151.651 81.6667 155.333 81.6667C159.015 81.6667 162 78.6819 162 75C162 71.3181 159.015 68.3333 155.333 68.3333C151.651 68.3333 148.667 71.3181 148.667 75Z' stroke='%235F6FFF' stroke-width='6.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M148.667 101.667H148C142.399 101.667 139.599 101.667 137.46 100.577C135.578 99.618 134.049 98.0882 133.09 96.2066C132 94.0675 132 91.2672 132 85.6667V75H115.333M148.667 101.667C148.667 105.349 151.651 108.333 155.333 108.333C159.015 108.333 162 105.349 162 101.667C162 97.9848 159.015 95 155.333 95C151.651 95 148.667 97.9848 148.667 101.667ZM115.333 75C115.333 78.6819 112.349 81.6667 108.667 81.6667C104.985 81.6667 102 78.6819 102 75C102 71.3181 104.985 68.3333 108.667 68.3333C112.349 68.3333 115.333 71.3181 115.333 75Z' stroke='white' stroke-width='6.66667' stroke-linecap='round'/%3E%3Ccircle cx='108.5' cy='74.5' r='5.5' fill='white'/%3E%3C/svg%3E)


'%3E%3Cpath d='M3.375 16.5V12.75M3.375 5.25V1.5M1.5 3.375H5.25M1.5 14.625H5.25M9.75 2.25L8.44937 5.63165C8.23786 6.18157 8.1321 6.45653 7.96765 6.68781C7.82189 6.8928 7.6428 7.07189 7.43781 7.21765C7.20653 7.3821 6.93157 7.48786 6.38165 7.69937L3 9L6.38165 10.3006C6.93157 10.5121 7.20653 10.6179 7.43781 10.7824C7.6428 10.9281 7.82189 11.1072 7.96765 11.3122C8.1321 11.5435 8.23786 11.8184 8.44937 12.3684L9.75 15.75L11.0506 12.3684C11.2621 11.8184 11.3679 11.5435 11.5324 11.3122C11.6781 11.1072 11.8572 10.9281 12.0622 10.7824C12.2935 10.6179 12.5684 10.5121 13.1184 10.3006L16.5 9L13.1184 7.69937C12.5684 7.48786 12.2935 7.3821 12.0622 7.21765C11.8572 7.07189 11.6781 6.8928 11.5324 6.68781C11.3679 6.45653 11.2621 6.18157 11.0506 5.63165L9.75 2.25Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_220_1217'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)
'%3E%3Cpath d='M4.5 4.5L6 3M6 3L4.5 1.5M6 3H4.5C2.84315 3 1.5 4.34315 1.5 6M13.5 13.5L12 15M12 15L13.5 16.5M12 15H13.5C15.1569 15 16.5 13.6569 16.5 12M7.64177 4.875C8.14132 2.93412 9.90318 1.5 12 1.5C14.4853 1.5 16.5 3.51472 16.5 6C16.5 8.0968 15.0659 9.85865 13.125 10.3582M10.5 12C10.5 14.4853 8.48528 16.5 6 16.5C3.51472 16.5 1.5 14.4853 1.5 12C1.5 9.51472 3.51472 7.5 6 7.5C8.48528 7.5 10.5 9.51472 10.5 12Z' stroke='%231A31FF' stroke-width='1.125' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_121_3926'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)
'%3E%3Cpath d='M9 1.5L10.509 5.42331C10.7205 5.97324 10.8262 6.2482 10.9907 6.47948C11.1364 6.68447 11.3155 6.86356 11.5205 7.00931C11.7518 7.17377 12.0268 7.27952 12.5767 7.49103L16.5 9L12.5767 10.509C12.0268 10.7205 11.7518 10.8262 11.5205 10.9907C11.3155 11.1364 11.1364 11.3155 10.9907 11.5205C10.8262 11.7518 10.7205 12.0268 10.509 12.5767L9 16.5L7.49103 12.5767C7.27952 12.0268 7.17377 11.7518 7.00931 11.5205C6.86356 11.3155 6.68447 11.1364 6.47948 10.9907C6.2482 10.8262 5.97324 10.7205 5.42331 10.509L1.5 9L5.42331 7.49103C5.97324 7.27952 6.2482 7.17377 6.47948 7.00931C6.68446 6.86356 6.86356 6.68446 7.00931 6.47948C7.17377 6.2482 7.27952 5.97324 7.49103 5.42331L9 1.5Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_121_3938'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)
' fill='%231A31FF'/%3E%3Cpath d='M112 55H112.033M112 95H112.033M109.333 68.3334H154.667C158.4 68.3334 160.267 68.3334 161.693 67.6067C162.948 66.9676 163.968 65.9477 164.607 64.6933C165.333 63.2672 165.333 61.4004 165.333 57.6667V52.3334C165.333 48.5997 165.333 46.7328 164.607 45.3068C163.968 44.0523 162.948 43.0325 161.693 42.3933C160.267 41.6667 158.4 41.6667 154.667 41.6667H109.333C105.6 41.6667 103.733 41.6667 102.307 42.3933C101.052 43.0325 100.032 44.0523 99.3933 45.3068C98.6667 46.7328 98.6667 48.5997 98.6667 52.3334V57.6667C98.6667 61.4004 98.6667 63.2672 99.3933 64.6933C100.032 65.9477 101.052 66.9676 102.307 67.6067C103.733 68.3334 105.6 68.3334 109.333 68.3334ZM109.333 108.333H154.667C158.4 108.333 160.267 108.333 161.693 107.607C162.948 106.968 163.968 105.948 164.607 104.693C165.333 103.267 165.333 101.4 165.333 97.6667V92.3334C165.333 88.5997 165.333 86.7328 164.607 85.3067C163.968 84.0523 162.948 83.0325 161.693 82.3933C160.267 81.6667 158.4 81.6667 154.667 81.6667H109.333C105.6 81.6667 103.733 81.6667 102.307 82.3933C101.052 83.0325 100.032 84.0523 99.3933 85.3067C98.6667 86.7328 98.6667 88.5997 98.6667 92.3334V97.6667C98.6667 101.4 98.6667 103.267 99.3933 104.693C100.032 105.948 101.052 106.968 102.307 107.607C103.733 108.333 105.6 108.333 109.333 108.333Z' stroke='%235F6FFF' stroke-width='6.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M152.25 95.25L138.75 81.75M143.25 70.5C143.25 79.1985 136.198 86.25 127.5 86.25C118.802 86.25 111.75 79.1985 111.75 70.5C111.75 61.8015 118.802 54.75 127.5 54.75C136.198 54.75 143.25 61.8015 143.25 70.5Z' stroke='white' stroke-width='4.5' stroke-linecap='round' stroke-linejoin='round'/%3E%3Ccircle cx='165' cy='42' r='7' fill='white'/%3E%3C/svg%3E)


'%3E%3Cpath d='M4.58981 14.939L4.94322 15.7526C5.04827 15.9948 5.21972 16.2005 5.43677 16.3449C5.65382 16.4894 5.90715 16.5662 6.16602 16.5662C6.42489 16.5662 6.67822 16.4894 6.89527 16.3449C7.11232 16.2005 7.28377 15.9948 7.38882 15.7526L7.74223 14.939C7.86803 14.6503 8.07965 14.4096 8.34691 14.2512C8.61587 14.0924 8.927 14.0248 9.2358 14.0579L10.1005 14.1522C10.3579 14.18 10.6177 14.1309 10.8483 14.0106C11.0789 13.8904 11.2705 13.7042 11.3999 13.4747C11.5294 13.2454 11.5911 12.9825 11.5775 12.7179C11.5639 12.4534 11.4756 12.1986 11.3233 11.9844L10.8113 11.2643C10.629 11.006 10.5316 10.6951 10.5332 10.3764C10.5331 10.0586 10.6314 9.74901 10.814 9.49199L11.326 8.77191C11.4783 8.55773 11.5666 8.30291 11.5802 8.03836C11.5938 7.77382 11.5321 7.51092 11.4026 7.28156C11.2732 7.05207 11.0816 6.86591 10.851 6.74567C10.6203 6.62543 10.3606 6.57626 10.1032 6.60413L9.23848 6.69835C8.92969 6.73155 8.61855 6.6639 8.3496 6.50509C8.0818 6.34583 7.87013 6.10387 7.74492 5.81391L7.38882 5.0003C7.28377 4.75811 7.11232 4.55233 6.89527 4.40791C6.67822 4.2635 6.42489 4.18665 6.16602 4.18669C5.90715 4.18665 5.65382 4.2635 5.43677 4.40791C5.21972 4.55233 5.04827 4.75811 4.94322 5.0003L4.58981 5.81391C4.4646 6.10387 4.25293 6.34583 3.98513 6.50509C3.71618 6.6639 3.40504 6.73155 3.09624 6.69835L2.22886 6.60413C1.97146 6.57626 1.7117 6.62543 1.48106 6.74567C1.25042 6.86591 1.05881 7.05207 0.929462 7.28156C0.799951 7.51092 0.738251 7.77382 0.751847 8.03836C0.765443 8.30291 0.85375 8.55773 1.00606 8.77191L1.51802 9.49199C1.7006 9.74901 1.79892 10.0586 1.79886 10.3764C1.79892 10.6942 1.7006 11.0039 1.51802 11.2609L1.00606 11.9809C0.85375 12.1951 0.765443 12.4499 0.751847 12.7145C0.738251 12.979 0.799951 13.2419 0.929462 13.4713C1.05893 13.7007 1.25057 13.8867 1.48117 14.007C1.71178 14.1272 1.97148 14.1764 2.22886 14.1487L3.09356 14.0545C3.40235 14.0213 3.71349 14.089 3.98244 14.2478C4.25124 14.4066 4.4639 14.6486 4.58981 14.939Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M6.16494 12.2334C7.16681 12.2334 7.97899 11.402 7.97899 10.3764C7.97899 9.35088 7.16681 8.51951 6.16494 8.51951C5.16307 8.51951 4.35089 9.35088 4.35089 10.3764C4.35089 11.402 5.16307 12.2334 6.16494 12.2334Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M14.126 7.98059C14.2161 7.77391 14.3676 7.6016 14.5589 7.48822C14.7515 7.37453 14.9742 7.3261 15.1953 7.34987L15.8143 7.41732C15.9986 7.43727 16.1846 7.40207 16.3497 7.31599C16.5148 7.22991 16.652 7.09664 16.7446 6.93234C16.8373 6.76814 16.8815 6.57993 16.8717 6.39054C16.862 6.20115 16.7988 6.01872 16.6898 5.86538L16.3232 5.34988C16.1927 5.16495 16.123 4.94236 16.1241 4.71423C16.1241 4.48673 16.1945 4.26506 16.3252 4.08105L16.6917 3.56554C16.8007 3.41221 16.8639 3.22978 16.8737 3.04039C16.8834 2.851 16.8392 2.66279 16.7465 2.49859C16.6539 2.33429 16.5167 2.20102 16.3516 2.11494C16.1865 2.02886 16.0005 1.99366 15.8163 2.01361L15.1972 2.08106C14.9762 2.10483 14.7534 2.0564 14.5609 1.94271C14.3691 1.82869 14.2176 1.65547 14.128 1.44788L13.873 0.865412C13.7978 0.692028 13.6751 0.544707 13.5197 0.441317C13.3643 0.337928 13.1829 0.282913 12.9976 0.282944C12.8123 0.282913 12.6309 0.337928 12.4755 0.441317C12.3202 0.544707 12.1974 0.692028 12.1222 0.865412L11.8692 1.44788C11.7796 1.65547 11.628 1.82869 11.4363 1.94271C11.2438 2.0564 11.021 2.10483 10.7999 2.08106L10.179 2.01361C9.9947 1.99366 9.80873 2.02886 9.64361 2.11494C9.47849 2.20102 9.34132 2.33429 9.24872 2.49859C9.156 2.66279 9.11183 2.851 9.12156 3.04039C9.13129 3.22978 9.19452 3.41221 9.30355 3.56554L9.67007 4.08105C9.80078 4.26506 9.87117 4.48673 9.87113 4.71423M14.2955 4.71423C14.2955 5.44843 13.7141 6.04362 12.9968 6.04362C12.2796 6.04362 11.6981 5.44843 11.6981 4.71423C11.6981 3.98003 12.2796 3.38485 12.9968 3.38485C13.7141 3.38485 14.2955 3.98003 14.2955 4.71423Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_220_1415'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)

' fill='%231A31FF'/%3E%3Cpath d='M113.667 96.3333C105.382 96.3333 98.6667 89.6176 98.6667 81.3333C98.6667 73.5214 104.638 67.1043 112.266 66.3979C113.826 56.9071 122.067 49.6666 132 49.6666C141.933 49.6666 150.174 56.9071 151.734 66.3979C159.362 67.1043 165.333 73.5214 165.333 81.3333C165.333 89.6176 158.618 96.3333 150.333 96.3333C135.701 96.3333 126.478 96.3333 113.667 96.3333Z' stroke='white' stroke-width='6.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3Ccircle cx='132' cy='75' r='53.4286' stroke='%235F6FFF' stroke-width='3.14286'/%3E%3Ccircle cx='92' cy='40' r='7' fill='white'/%3E%3Ccircle cx='185' cy='75' r='7' fill='white'/%3E%3Ccircle cx='92' cy='111' r='7' fill='white'/%3E%3C/svg%3E)


'%3E%3Cpath d='M12.7271 8.32943C13.5367 8.32943 14.193 7.67312 14.193 6.86352C14.193 6.05392 13.5367 5.39761 12.7271 5.39761C11.9175 5.39761 11.2612 6.05392 11.2612 6.86352C11.2612 7.67312 11.9175 8.32943 12.7271 8.32943Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M5.39755 14.1932C6.20715 14.1932 6.86346 13.5369 6.86346 12.7273C6.86346 11.9177 6.20715 11.2614 5.39755 11.2614C4.58795 11.2614 3.93164 11.9177 3.93164 12.7273C3.93164 13.5369 4.58795 14.1932 5.39755 14.1932Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M11.2613 17.1251V11.9944L5.39771 6.1308V1.00012' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M5.39771 11.2613V6.13058' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M16.392 1H1.73295C1.32815 1 1 1.32815 1 1.73295V16.392C1 16.7968 1.32815 17.125 1.73295 17.125H16.392C16.7968 17.125 17.125 16.7968 17.125 16.392V1.73295C17.125 1.32815 16.7968 1 16.392 1Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M9.79541 1.00012V3.93194L11.691 5.82754' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_220_930'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)


'%3E%3Cpath d='M3.975 3.975L5.5875 2.3625M5.5875 2.3625L3.975 0.75M5.5875 2.3625H3.975C2.19388 2.3625 0.75 3.80638 0.75 5.5875M13.65 13.65L12.0375 15.2625M12.0375 15.2625L13.65 16.875M12.0375 15.2625H13.65C15.4311 15.2625 16.875 13.8186 16.875 12.0375' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M4.33618 15.0599L4.61676 15.7059C4.70017 15.8981 4.8363 16.0615 5.00862 16.1762C5.18094 16.2908 5.38207 16.3518 5.5876 16.3518C5.79313 16.3518 5.99425 16.2908 6.16658 16.1762C6.3389 16.0615 6.47502 15.8981 6.55843 15.7059L6.83901 15.0599C6.93889 14.8307 7.1069 14.6396 7.3191 14.5139C7.53263 14.3878 7.77966 14.3341 8.02482 14.3604L8.71134 14.4352C8.91569 14.4574 9.12193 14.4183 9.30505 14.3229C9.48817 14.2274 9.64029 14.0796 9.74298 13.8974C9.84581 13.7153 9.89479 13.5066 9.884 13.2965C9.8732 13.0865 9.80309 12.8842 9.68217 12.7141L9.2757 12.1425C9.13097 11.9374 9.05363 11.6905 9.05486 11.4375C9.05482 11.1852 9.13288 10.9394 9.27784 10.7353L9.68431 10.1636C9.80523 9.99359 9.87534 9.79127 9.88613 9.58124C9.89693 9.3712 9.84794 9.16248 9.74512 8.98038C9.64242 8.79818 9.4903 8.65038 9.30718 8.55492C9.12407 8.45945 8.91783 8.42041 8.71347 8.44254L8.02695 8.51735C7.78179 8.5437 7.53476 8.49 7.32123 8.36391C7.10862 8.23747 6.94056 8.04537 6.84115 7.81515L6.55843 7.16919C6.47502 6.97691 6.3389 6.81353 6.16658 6.69888C5.99425 6.58422 5.79313 6.5232 5.5876 6.52324C5.38207 6.5232 5.18094 6.58422 5.00862 6.69888C4.8363 6.81353 4.70017 6.97691 4.61676 7.16919L4.33618 7.81515C4.23677 8.04537 4.06871 8.23747 3.8561 8.36391C3.64257 8.49 3.39554 8.5437 3.15038 8.51735L2.46172 8.44254C2.25737 8.42041 2.05113 8.45945 1.86801 8.55492C1.6849 8.65038 1.53277 8.79818 1.43008 8.98038C1.32726 9.16248 1.27827 9.3712 1.28906 9.58124C1.29986 9.79127 1.36997 9.99359 1.49089 10.1636L1.89736 10.7353C2.04232 10.9394 2.12038 11.1852 2.12033 11.4375C2.12038 11.6898 2.04232 11.9357 1.89736 12.1397L1.49089 12.7114C1.36997 12.8815 1.29986 13.0838 1.28906 13.2938C1.27827 13.5038 1.32726 13.7126 1.43008 13.8947C1.53287 14.0768 1.68502 14.2245 1.86811 14.3199C2.0512 14.4154 2.25738 14.4545 2.46172 14.4325L3.14824 14.3577C3.39341 14.3313 3.64043 14.3851 3.85397 14.5111C4.06738 14.6372 4.23621 14.8294 4.33618 15.0599Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M5.58674 12.9118C6.38217 12.9118 7.02699 12.2518 7.02699 11.4375C7.02699 10.6233 6.38217 9.96324 5.58674 9.96324C4.79131 9.96324 4.14649 10.6233 4.14649 11.4375C4.14649 12.2518 4.79131 12.9118 5.58674 12.9118Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M13.7396 8.55338C13.8379 8.32775 14.0033 8.13965 14.2122 8.01588C14.4224 7.89176 14.6655 7.8389 14.9069 7.86484L15.5826 7.93848C15.7838 7.96026 15.9868 7.92183 16.1671 7.82786C16.3473 7.73388 16.4971 7.5884 16.5982 7.40904C16.6994 7.22979 16.7476 7.02432 16.737 6.81757C16.7264 6.61082 16.6573 6.41166 16.5383 6.24428L16.1382 5.68151C15.9957 5.47964 15.9196 5.23664 15.9208 4.9876C15.9208 4.73924 15.9976 4.49725 16.1403 4.29638L16.5404 3.73361C16.6594 3.56622 16.7285 3.36707 16.7391 3.16032C16.7497 2.95357 16.7015 2.7481 16.6003 2.56885C16.4992 2.38949 16.3494 2.24401 16.1692 2.15003C15.9889 2.05606 15.7859 2.01763 15.5847 2.03941L14.909 2.11305C14.6676 2.13899 14.4245 2.08613 14.2143 1.96201C14.005 1.83754 13.8395 1.64845 13.7417 1.42183L13.4634 0.785963C13.3813 0.596685 13.2473 0.435859 13.0776 0.322992C12.908 0.210126 12.71 0.150067 12.5077 0.150101C12.3054 0.150067 12.1074 0.210126 11.9378 0.322992C11.7682 0.435859 11.6342 0.596685 11.5521 0.785963L11.2759 1.42183C11.178 1.64845 11.0126 1.83754 10.8033 1.96201C10.5931 2.08613 10.3499 2.13899 10.1086 2.11305L9.43068 2.03941C9.22952 2.01763 9.0265 2.05606 8.84625 2.15003C8.666 2.24401 8.51625 2.38949 8.41516 2.56885C8.31394 2.7481 8.26572 2.95357 8.27635 3.16032C8.28697 3.36707 8.35599 3.56622 8.47502 3.73361L8.87514 4.29638C9.01783 4.49725 9.09467 4.73924 9.09463 4.9876M13.9246 4.9876C13.9246 5.7891 13.2899 6.43885 12.5069 6.43885C11.7239 6.43885 11.0891 5.7891 11.0891 4.9876C11.0891 4.1861 11.7239 3.53635 12.5069 3.53635C13.2899 3.53635 13.9246 4.1861 13.9246 4.9876Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_220_78'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)
' fill='%231A31FF'/%3E%3Cpath d='M162.001 105V78.75M132.001 105V67.5M102.001 105L102.001 90M137.276 48.8531L156.657 56.1213M127.496 50.2535L106.502 65.9994M165.978 54.1475C168.175 56.3442 168.175 59.9058 165.978 62.1025C163.782 64.2992 160.22 64.2992 158.023 62.1025C155.827 59.9058 155.827 56.3442 158.023 54.1475C160.22 51.9508 163.782 51.9508 165.978 54.1475ZM105.978 65.3975C108.175 67.5942 108.175 71.1558 105.978 73.3525C103.782 75.5492 100.22 75.5492 98.0233 73.3525C95.8266 71.1558 95.8266 67.5942 98.0233 65.3975C100.22 63.2008 103.782 63.2008 105.978 65.3975ZM135.978 42.8975C138.175 45.0942 138.175 48.6558 135.978 50.8525C133.782 53.0492 130.22 53.0492 128.023 50.8525C125.827 48.6558 125.827 45.0942 128.023 42.8975C130.22 40.7008 133.782 40.7008 135.978 42.8975Z' stroke='%235F6FFF' stroke-width='7.5' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M137.276 48.8531L156.657 56.1213M127.496 50.2535L106.502 65.9994M165.978 54.1475C168.175 56.3442 168.175 59.9058 165.978 62.1025C163.782 64.2992 160.22 64.2992 158.023 62.1025C155.827 59.9058 155.827 56.3442 158.023 54.1475C160.22 51.9508 163.782 51.9508 165.978 54.1475ZM105.978 65.3975C108.175 67.5942 108.175 71.1558 105.978 73.3525C103.782 75.5492 100.22 75.5492 98.0233 73.3525C95.8266 71.1558 95.8266 67.5942 98.0233 65.3975C100.22 63.2008 103.782 63.2008 105.978 65.3975ZM135.978 42.8975C138.175 45.0942 138.175 48.6558 135.978 50.8525C133.782 53.0492 130.22 53.0492 128.023 50.8525C125.827 48.6558 125.827 45.0942 128.023 42.8975C130.22 40.7008 133.782 40.7008 135.978 42.8975Z' stroke='white' stroke-width='7.5' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/svg%3E)


' fill='%231A31FF'/%3E%3Cg clip-path='url(%23clip0_1139_22951)'%3E%3Cpath d='M167.062 42.625H96.9375C95.1771 42.625 93.75 44.0521 93.75 45.8125V103.188C93.75 104.948 95.1771 106.375 96.9375 106.375H167.062C168.823 106.375 170.25 104.948 170.25 103.188V45.8125C170.25 44.0521 168.823 42.625 167.062 42.625Z' stroke='%235F6FFF' stroke-width='6.375' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M108.094 61.75C110.734 61.75 112.875 59.6094 112.875 56.9688C112.875 54.3281 110.734 52.1875 108.094 52.1875C105.453 52.1875 103.312 54.3281 103.312 56.9688C103.312 59.6094 105.453 61.75 108.094 61.75Z' fill='%235F6FFF'/%3E%3Cpath d='M124.031 61.75C126.672 61.75 128.812 59.6094 128.812 56.9688C128.812 54.3281 126.672 52.1875 124.031 52.1875C121.391 52.1875 119.25 54.3281 119.25 56.9688C119.25 59.6094 121.391 61.75 124.031 61.75Z' fill='%235F6FFF'/%3E%3C/g%3E%3Cpath d='M169.695 82.7879C170.576 82.3134 171.017 82.0762 171.128 81.7908C171.225 81.5431 171.197 81.2642 171.055 81.0399C170.89 80.7816 170.412 80.6343 169.455 80.3397L150.742 74.5752C149.961 74.3346 149.57 74.2143 149.306 74.3111C149.077 74.3954 148.895 74.5765 148.811 74.8063C148.714 75.0701 148.835 75.4608 149.075 76.242L154.84 94.9554C155.134 95.9117 155.282 96.3899 155.54 96.5545C155.764 96.6974 156.043 96.7247 156.291 96.628C156.576 96.5166 156.813 96.0761 157.288 95.195L161.441 87.4825C161.511 87.3516 161.547 87.2861 161.592 87.2288C161.632 87.178 161.678 87.132 161.729 87.0918C161.786 87.0465 161.852 87.0112 161.983 86.9407L169.695 82.7879Z' fill='white'/%3E%3Cpath d='M150 66.3333V63.8333M143.434 68.9344L141.667 67.1666M143.434 82.1666L141.667 83.9344M156.667 68.9344L158.434 67.1666M140.833 75.4999H138.333M161.441 87.4825L157.288 95.195C156.813 96.0761 156.576 96.5166 156.291 96.628C156.043 96.7247 155.764 96.6974 155.54 96.5545C155.282 96.3899 155.134 95.9117 154.84 94.9554L149.075 76.242C148.835 75.4608 148.714 75.0701 148.811 74.8063C148.895 74.5765 149.077 74.3954 149.306 74.3111C149.57 74.2143 149.961 74.3346 150.742 74.5752L169.455 80.3397C170.412 80.6343 170.89 80.7816 171.055 81.0399C171.197 81.2642 171.225 81.5431 171.128 81.7908C171.017 82.0762 170.576 82.3134 169.695 82.7879L161.983 86.9407C161.852 87.0112 161.786 87.0465 161.729 87.0918C161.678 87.132 161.632 87.178 161.592 87.2288C161.547 87.2861 161.511 87.3516 161.441 87.4825Z' stroke='white' stroke-width='3.33333' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cdefs%3E%3CclipPath id='clip0_1139_22951'%3E%3Crect width='102' height='102' fill='white' transform='translate(81 23.5)'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)

'%3E%3Cpath d='M15.9 16.5C16.11 16.5 16.215 16.5 16.2952 16.4591C16.3658 16.4232 16.4232 16.3658 16.4591 16.2952C16.5 16.215 16.5 16.11 16.5 15.9V8.1C16.5 7.88998 16.5 7.78497 16.4591 7.70475C16.4232 7.63419 16.3658 7.57683 16.2952 7.54087C16.215 7.5 16.11 7.5 15.9 7.5L14.1 7.5C13.89 7.5 13.785 7.5 13.7048 7.54087C13.6342 7.57683 13.5768 7.63419 13.5409 7.70475C13.5 7.78497 13.5 7.88998 13.5 8.1V9.9C13.5 10.11 13.5 10.215 13.4591 10.2952C13.4232 10.3658 13.3658 10.4232 13.2952 10.4591C13.215 10.5 13.11 10.5 12.9 10.5H11.1C10.89 10.5 10.785 10.5 10.7048 10.5409C10.6342 10.5768 10.5768 10.6342 10.5409 10.7048C10.5 10.785 10.5 10.89 10.5 11.1V12.9C10.5 13.11 10.5 13.215 10.4591 13.2952C10.4232 13.3658 10.3658 13.4232 10.2952 13.4591C10.215 13.5 10.11 13.5 9.9 13.5H8.1C7.88998 13.5 7.78497 13.5 7.70475 13.5409C7.63419 13.5768 7.57683 13.6342 7.54087 13.7048C7.5 13.785 7.5 13.89 7.5 14.1V15.9C7.5 16.11 7.5 16.215 7.54087 16.2952C7.57683 16.3658 7.63419 16.4232 7.70475 16.4591C7.78497 16.5 7.88998 16.5 8.1 16.5L15.9 16.5Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M7.5 5.1C7.5 4.88998 7.5 4.78497 7.54087 4.70475C7.57683 4.63419 7.63419 4.57683 7.70475 4.54087C7.78497 4.5 7.88998 4.5 8.1 4.5H9.9C10.11 4.5 10.215 4.5 10.2952 4.54087C10.3658 4.57683 10.4232 4.63419 10.4591 4.70475C10.5 4.78497 10.5 4.88998 10.5 5.1V6.9C10.5 7.11002 10.5 7.21503 10.4591 7.29525C10.4232 7.36581 10.3658 7.42317 10.2952 7.45913C10.215 7.5 10.11 7.5 9.9 7.5H8.1C7.88998 7.5 7.78497 7.5 7.70475 7.45913C7.63419 7.42317 7.57683 7.36581 7.54087 7.29525C7.5 7.21503 7.5 7.11002 7.5 6.9V5.1Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M2.25 9.6C2.25 9.38998 2.25 9.28497 2.29087 9.20475C2.32683 9.13419 2.38419 9.07683 2.45475 9.04087C2.53497 9 2.63998 9 2.85 9H4.65C4.86002 9 4.96503 9 5.04525 9.04087C5.11581 9.07683 5.17317 9.13419 5.20913 9.20475C5.25 9.28497 5.25 9.38998 5.25 9.6V11.4C5.25 11.61 5.25 11.715 5.20913 11.7952C5.17317 11.8658 5.11581 11.9232 5.04525 11.9591C4.96503 12 4.86002 12 4.65 12H2.85C2.63998 12 2.53497 12 2.45475 11.9591C2.38419 11.9232 2.32683 11.8658 2.29087 11.7952C2.25 11.715 2.25 11.61 2.25 11.4V9.6Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M1.5 2.1C1.5 1.88998 1.5 1.78497 1.54087 1.70475C1.57683 1.63419 1.63419 1.57683 1.70475 1.54087C1.78497 1.5 1.88998 1.5 2.1 1.5H3.9C4.11002 1.5 4.21503 1.5 4.29525 1.54087C4.36581 1.57683 4.42317 1.63419 4.45913 1.70475C4.5 1.78497 4.5 1.88998 4.5 2.1V3.9C4.5 4.11002 4.5 4.21503 4.45913 4.29525C4.42317 4.36581 4.36581 4.42317 4.29525 4.45913C4.21503 4.5 4.11002 4.5 3.9 4.5H2.1C1.88998 4.5 1.78497 4.5 1.70475 4.45913C1.63419 4.42317 1.57683 4.36581 1.54087 4.29525C1.5 4.21503 1.5 4.11002 1.5 3.9V2.1Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_441_6429'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E%0A)

'%3E%3Cpath d='M2.01506 11.7338L3.44621 10.9077C3.52373 10.8629 3.6147 10.8474 3.70268 10.8638L6.51855 11.3908C6.74996 11.4341 6.96358 11.256 6.96254 11.0206L6.95157 8.55334C6.95127 8.4863 6.96895 8.42042 7.00276 8.36253L8.4238 5.92966C8.49776 5.80304 8.49113 5.64494 8.40684 5.52495L6.01419 2.11926M14.2502 3.64429C10.1252 5.62503 12.375 8.25003 13.1252 8.62503C14.533 9.32881 16.4907 9.37499 16.4907 9.37499C16.4969 9.25076 16.5 9.12575 16.5 9C16.5 4.85786 13.1421 1.5 9 1.5C4.85786 1.5 1.5 4.85786 1.5 9C1.5 13.1421 4.85786 16.5 9 16.5C9.12575 16.5 9.25077 16.4969 9.375 16.4908M12.5683 16.4548L10.1933 10.1933L16.4548 12.5683L13.6782 13.6782L12.5683 16.4548Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_528_18011'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E%0A)
' fill='%231A31FF'/%3E%3Cpath d='M162 67.8333H102M162 94.5H102M162 54.5H102M162 81.1667H102' stroke='%235F6FFF' stroke-width='6.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M162 54.5H102' stroke='white' stroke-width='6.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M79.9993 59.0839C79.9993 60.023 79.9994 60.4926 80.1933 60.7403C80.362 60.9558 80.6186 61.0841 80.8923 61.0898C81.2067 61.0963 81.5824 60.8146 82.3338 60.2511L89.3856 54.9622C89.9136 54.5662 90.1776 54.3682 90.272 54.1255C90.3547 53.9129 90.3547 53.677 90.272 53.4644C90.1776 53.2217 89.9136 53.0237 89.3856 52.6277L82.3338 47.3388C81.5824 46.7753 81.2067 46.4936 80.8923 46.5001C80.6186 46.5058 80.362 46.6341 80.1933 46.8496C79.9994 47.0973 79.9993 47.5669 79.9993 48.506V59.0839Z' fill='white' stroke='white' stroke-width='3.64752' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/svg%3E)


'%3E%3Cpath d='M4.5 4.5L6 3M6 3L4.5 1.5M6 3H4.5C2.84315 3 1.5 4.34315 1.5 6M13.5 13.5L12 15M12 15L13.5 16.5M12 15H13.5C15.1569 15 16.5 13.6569 16.5 12M7.64177 4.875C8.14132 2.93412 9.90318 1.5 12 1.5C14.4853 1.5 16.5 3.51472 16.5 6C16.5 8.0968 15.0659 9.85865 13.125 10.3582M10.5 12C10.5 14.4853 8.48528 16.5 6 16.5C3.51472 16.5 1.5 14.4853 1.5 12C1.5 9.51472 3.51472 7.5 6 7.5C8.48528 7.5 10.5 9.51472 10.5 12Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_220_357'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)


'%3E%3Cpath d='M8.25 3.375H13.725C14.5651 3.375 14.9851 3.375 15.306 3.53849C15.5882 3.6823 15.8177 3.91177 15.9615 4.19401C16.125 4.51488 16.125 4.93492 16.125 5.775V6.75C16.125 7.44891 16.125 7.79837 16.0108 8.07403C15.8586 8.44157 15.5666 8.73358 15.199 8.88582C14.9234 9 14.5739 9 13.875 9M9.75 14.625H4.275C3.43492 14.625 3.01488 14.625 2.69401 14.4615C2.41177 14.3177 2.1823 14.0882 2.03849 13.806C1.875 13.4851 1.875 13.0651 1.875 12.225V11.25C1.875 10.5511 1.875 10.2016 1.98918 9.92598C2.14142 9.55843 2.43343 9.26642 2.80097 9.11418C3.07663 9 3.42609 9 4.125 9M7.725 10.875H10.275C10.485 10.875 10.59 10.875 10.6702 10.8341C10.7408 10.7982 10.7982 10.7408 10.8341 10.6702C10.875 10.59 10.875 10.485 10.875 10.275V7.725C10.875 7.51498 10.875 7.40997 10.8341 7.32975C10.7982 7.25919 10.7408 7.20183 10.6702 7.16587C10.59 7.125 10.485 7.125 10.275 7.125H7.725C7.51498 7.125 7.40997 7.125 7.32975 7.16587C7.25919 7.20183 7.20183 7.25919 7.16587 7.32975C7.125 7.40997 7.125 7.51498 7.125 7.725V10.275C7.125 10.485 7.125 10.59 7.16587 10.6702C7.20183 10.7408 7.25919 10.7982 7.32975 10.8341C7.40997 10.875 7.51498 10.875 7.725 10.875ZM13.35 16.5H15.9C16.11 16.5 16.215 16.5 16.2952 16.4591C16.3658 16.4232 16.4232 16.3658 16.4591 16.2952C16.5 16.215 16.5 16.11 16.5 15.9V13.35C16.5 13.14 16.5 13.035 16.4591 12.9548C16.4232 12.8842 16.3658 12.8268 16.2952 12.7909C16.215 12.75 16.11 12.75 15.9 12.75H13.35C13.14 12.75 13.035 12.75 12.9548 12.7909C12.8842 12.8268 12.8268 12.8842 12.7909 12.9548C12.75 13.035 12.75 13.14 12.75 13.35V15.9C12.75 16.11 12.75 16.215 12.7909 16.2952C12.8268 16.3658 12.8842 16.4232 12.9548 16.4591C13.035 16.5 13.14 16.5 13.35 16.5ZM2.1 5.25H4.65C4.86002 5.25 4.96503 5.25 5.04525 5.20913C5.11581 5.17317 5.17317 5.11581 5.20913 5.04525C5.25 4.96503 5.25 4.86002 5.25 4.65V2.1C5.25 1.88998 5.25 1.78497 5.20913 1.70475C5.17317 1.63419 5.11581 1.57683 5.04525 1.54087C4.96503 1.5 4.86002 1.5 4.65 1.5H2.1C1.88998 1.5 1.78497 1.5 1.70475 1.54087C1.63419 1.57683 1.57683 1.63419 1.54087 1.70475C1.5 1.78497 1.5 1.88998 1.5 2.1V4.65C1.5 4.86002 1.5 4.96503 1.54087 5.04525C1.57683 5.11581 1.63419 5.17317 1.70475 5.20913C1.78497 5.25 1.88998 5.25 2.1 5.25Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_220_448'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)


'%3E%3Cpath d='M4.58981 14.939L4.94322 15.7526C5.04827 15.9948 5.21972 16.2005 5.43677 16.3449C5.65382 16.4894 5.90715 16.5662 6.16602 16.5662C6.42489 16.5662 6.67822 16.4894 6.89527 16.3449C7.11232 16.2005 7.28377 15.9948 7.38882 15.7526L7.74223 14.939C7.86803 14.6503 8.07965 14.4096 8.34691 14.2512C8.61587 14.0924 8.927 14.0248 9.2358 14.0579L10.1005 14.1522C10.3579 14.18 10.6177 14.1309 10.8483 14.0106C11.0789 13.8904 11.2705 13.7042 11.3999 13.4747C11.5294 13.2454 11.5911 12.9825 11.5775 12.7179C11.5639 12.4534 11.4756 12.1986 11.3233 11.9844L10.8113 11.2643C10.629 11.006 10.5316 10.6951 10.5332 10.3764C10.5331 10.0586 10.6314 9.74901 10.814 9.49199L11.326 8.77191C11.4783 8.55773 11.5666 8.30291 11.5802 8.03836C11.5938 7.77382 11.5321 7.51092 11.4026 7.28156C11.2732 7.05207 11.0816 6.86591 10.851 6.74567C10.6203 6.62543 10.3606 6.57626 10.1032 6.60413L9.23848 6.69835C8.92969 6.73155 8.61855 6.6639 8.3496 6.50509C8.0818 6.34583 7.87013 6.10387 7.74492 5.81391L7.38882 5.0003C7.28377 4.75811 7.11232 4.55233 6.89527 4.40791C6.67822 4.2635 6.42489 4.18665 6.16602 4.18669C5.90715 4.18665 5.65382 4.2635 5.43677 4.40791C5.21972 4.55233 5.04827 4.75811 4.94322 5.0003L4.58981 5.81391C4.4646 6.10387 4.25293 6.34583 3.98513 6.50509C3.71618 6.6639 3.40504 6.73155 3.09624 6.69835L2.22886 6.60413C1.97146 6.57626 1.7117 6.62543 1.48106 6.74567C1.25042 6.86591 1.05881 7.05207 0.929462 7.28156C0.799951 7.51092 0.738251 7.77382 0.751847 8.03836C0.765443 8.30291 0.85375 8.55773 1.00606 8.77191L1.51802 9.49199C1.7006 9.74901 1.79892 10.0586 1.79886 10.3764C1.79892 10.6942 1.7006 11.0039 1.51802 11.2609L1.00606 11.9809C0.85375 12.1951 0.765443 12.4499 0.751847 12.7145C0.738251 12.979 0.799951 13.2419 0.929462 13.4713C1.05893 13.7007 1.25057 13.8867 1.48117 14.007C1.71178 14.1272 1.97148 14.1764 2.22886 14.1487L3.09356 14.0545C3.40235 14.0213 3.71349 14.089 3.98244 14.2478C4.25124 14.4066 4.4639 14.6486 4.58981 14.939Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M6.16494 12.2334C7.16681 12.2334 7.97899 11.402 7.97899 10.3764C7.97899 9.35088 7.16681 8.51951 6.16494 8.51951C5.16307 8.51951 4.35089 9.35088 4.35089 10.3764C4.35089 11.402 5.16307 12.2334 6.16494 12.2334Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M14.1262 7.98059C14.2162 7.77391 14.3677 7.6016 14.5591 7.48822C14.7516 7.37453 14.9744 7.3261 15.1954 7.34987L15.8145 7.41732C15.9987 7.43727 16.1847 7.40207 16.3498 7.31599C16.5149 7.22991 16.6521 7.09664 16.7447 6.93234C16.8374 6.76814 16.8816 6.57993 16.8719 6.39054C16.8621 6.20115 16.7989 6.01872 16.6899 5.86538L16.3234 5.34988C16.1929 5.16495 16.1231 4.94236 16.1242 4.71423C16.1242 4.48673 16.1946 4.26506 16.3253 4.08105L16.6918 3.56554C16.8008 3.41221 16.8641 3.22978 16.8738 3.04039C16.8835 2.851 16.8394 2.66279 16.7466 2.49859C16.654 2.33429 16.5169 2.20102 16.3517 2.11494C16.1866 2.02886 16.0007 1.99366 15.8164 2.01361L15.1973 2.08106C14.9763 2.10483 14.7535 2.0564 14.561 1.94271C14.3693 1.82869 14.2177 1.65547 14.1281 1.44788L13.8732 0.865412C13.7979 0.692028 13.6752 0.544707 13.5198 0.441317C13.3644 0.337928 13.1831 0.282913 12.9977 0.282944C12.8124 0.282913 12.6311 0.337928 12.4757 0.441317C12.3203 0.544707 12.1975 0.692028 12.1223 0.865412L11.8693 1.44788C11.7797 1.65547 11.6281 1.82869 11.4364 1.94271C11.2439 2.0564 11.0211 2.10483 10.8001 2.08106L10.1791 2.01361C9.99482 1.99366 9.80885 2.02886 9.64373 2.11494C9.47861 2.20102 9.34144 2.33429 9.24884 2.49859C9.15612 2.66279 9.11195 2.851 9.12168 3.04039C9.13142 3.22978 9.19464 3.41221 9.30367 3.56554L9.67019 4.08105C9.8009 4.26506 9.87129 4.48673 9.87125 4.71423M14.2957 4.71423C14.2957 5.44843 13.7142 6.04362 12.997 6.04362C12.2797 6.04362 11.6983 5.44843 11.6983 4.71423C11.6983 3.98003 12.2797 3.38485 12.997 3.38485C13.7142 3.38485 14.2957 3.98003 14.2957 4.71423Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_220_424'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)


'%3E%3Cpath d='M12.7271 8.32943C13.5367 8.32943 14.193 7.67312 14.193 6.86352C14.193 6.05392 13.5367 5.39761 12.7271 5.39761C11.9175 5.39761 11.2612 6.05392 11.2612 6.86352C11.2612 7.67312 11.9175 8.32943 12.7271 8.32943Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M5.39755 14.1932C6.20715 14.1932 6.86346 13.5369 6.86346 12.7273C6.86346 11.9177 6.20715 11.2614 5.39755 11.2614C4.58795 11.2614 3.93164 11.9177 3.93164 12.7273C3.93164 13.5369 4.58795 14.1932 5.39755 14.1932Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M11.2613 17.1251V11.9944L5.39771 6.1308V1.00012' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M5.39771 11.2613V6.13058' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M16.392 1H1.73295C1.32815 1 1 1.32815 1 1.73295V16.392C1 16.7968 1.32815 17.125 1.73295 17.125H16.392C16.7968 17.125 17.125 16.7968 17.125 16.392V1.73295C17.125 1.32815 16.7968 1 16.392 1Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M9.79541 1.00012V3.93194L11.691 5.82754' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_220_242'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)


' fill='%231A31FF'/%3E%3Cpath d='M29.7152 27.4452C29.7152 24.0541 29.7152 22.3585 30.3752 21.0633C30.9557 19.924 31.882 18.9977 33.0213 18.4172C34.3165 17.7573 36.0121 17.7573 39.4032 17.7573H40.0087C41.7042 17.7573 42.552 17.7573 43.1996 18.0872C43.7692 18.3775 44.2324 18.8406 44.5226 19.4103C44.8526 20.0579 44.8526 20.9057 44.8526 22.6012V35.6194C44.8526 37.3149 44.8526 38.1627 44.5226 38.8103C44.2324 39.3799 43.7692 39.8431 43.1996 40.1333C42.552 40.4633 41.7042 40.4633 40.0087 40.4633H37.9275C36.0319 40.4633 35.0841 40.4633 34.2238 40.7246C33.4621 40.9559 32.7535 41.3351 32.1386 41.8405C31.444 42.4114 30.9182 43.2001 29.8667 44.7773L29.7152 45.0045L29.5638 44.7773C28.5123 43.2001 27.9865 42.4114 27.2919 41.8405C26.677 41.3351 25.9684 40.9559 25.2067 40.7246C24.3464 40.4633 23.3986 40.4633 21.503 40.4633H19.4218C17.7263 40.4633 16.8785 40.4633 16.2309 40.1333C15.6613 39.8431 15.1981 39.3799 14.9079 38.8103C14.5779 38.1627 14.5779 37.3149 14.5779 35.6194V22.6012C14.5779 20.9057 14.5779 20.0579 14.9079 19.4103C15.1981 18.8406 15.6613 18.3775 16.2309 18.0872C16.8785 17.7573 17.7263 17.7573 19.4218 17.7573H20.0273C23.4184 17.7573 25.114 17.7573 26.4092 18.4172C27.5485 18.9977 28.4748 19.924 29.0553 21.0633C29.7152 22.3585 29.7152 24.0541 29.7152 27.4452ZM29.7152 45.0045V27.4452' stroke='%235F6FFF' stroke-width='3.02747' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M38.7512 26.8681C38.8545 26.5994 38.9061 26.4651 38.9736 26.3394C39.0335 26.2278 39.1027 26.1214 39.1803 26.0213C39.2678 25.9086 39.3695 25.8069 39.5731 25.6033L48.1104 17.0661C48.9464 16.2301 50.3018 16.2301 51.1378 17.0661C51.9738 17.9021 51.9738 19.2575 51.1378 20.0936L42.6005 28.6308C42.397 28.8343 42.2953 28.9361 42.1826 29.0235C42.0825 29.1012 41.9761 29.1704 41.8644 29.2303C41.7388 29.2977 41.6045 29.3494 41.3358 29.4527L37.1357 31.0681L38.7512 26.8681Z' fill='white'/%3E%3Cpath d='M38.6935 27.0181C38.8049 26.7283 38.8607 26.5834 38.9563 26.517C39.0398 26.459 39.1432 26.4371 39.2431 26.4561C39.3574 26.478 39.4672 26.5878 39.6868 26.8073L41.3966 28.5172C41.6162 28.7367 41.7259 28.8465 41.7478 28.9608C41.7668 29.0607 41.7449 29.1641 41.6869 29.2476C41.6205 29.3432 41.4756 29.399 41.1858 29.5104L37.1357 31.0681L38.6935 27.0181Z' fill='white'/%3E%3Cpath d='M37.1357 31.0681L41.3358 29.4527C41.6045 29.3494 41.7388 29.2977 41.8644 29.2303C41.9761 29.1704 42.0825 29.1012 42.1826 29.0235C42.2953 28.9361 42.397 28.8343 42.6005 28.6308L51.1378 20.0936C51.9738 19.2575 51.9738 17.9021 51.1378 17.0661C50.3018 16.2301 48.9464 16.2301 48.1104 17.0661L39.5731 25.6033C39.3695 25.8069 39.2678 25.9086 39.1803 26.0213C39.1027 26.1214 39.0335 26.2278 38.9736 26.3394C38.9061 26.4651 38.8545 26.5994 38.7512 26.8681L37.1357 31.0681ZM37.1357 31.0681L38.6935 27.0181C38.8049 26.7283 38.8607 26.5834 38.9563 26.517C39.0398 26.459 39.1432 26.4371 39.2431 26.4561C39.3574 26.478 39.4672 26.5878 39.6868 26.8073L41.3966 28.5172C41.6162 28.7367 41.7259 28.8465 41.7478 28.9608C41.7668 29.0607 41.7449 29.1641 41.6869 29.2476C41.6205 29.3432 41.4756 29.399 41.1858 29.5104L37.1357 31.0681Z' stroke='white' stroke-width='1.51374' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/svg%3E)
' fill='white'/%3E%3Crect width='110.56' height='62.19' transform='translate(-25.0007 -0.999786)' fill='%231A31FF'/%3E%3Cpath d='M23.0388 38.8807H37.5169M23.0388 33.8134H30.4847M25.3139 18.6114H22.3149H20.1432C18.544 18.6114 17.2476 19.9078 17.2476 21.507V41.7763C17.2476 43.3755 18.544 44.672 20.1432 44.672H40.4125C42.0117 44.672 43.3081 43.3755 43.3081 41.7763V21.507C43.3081 19.9078 42.0117 18.6114 40.4125 18.6114H38.2408H35.2418' stroke='%235F6FFF' stroke-width='2.89562' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M30.2776 23.5756C32.6764 23.5756 34.621 21.6309 34.621 19.2321C34.621 16.8333 32.6764 14.8887 30.2776 14.8887C27.8788 14.8887 25.9341 16.8333 25.9341 19.2321C25.9341 21.6309 27.8788 23.5756 30.2776 23.5756ZM30.2776 23.5756L30.3086 23.5753L25.6861 28.1978L21.5911 24.1028L25.9626 19.7312M30.2776 23.5756L34.9002 28.1978L38.9952 24.1028L34.6236 19.7312' stroke='white' stroke-width='2.89562' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/svg%3E)
' fill='%231A31FF'/%3E%3Cg clip-path='url(%23clip0_1146_27749)'%3E%3Cpath d='M27.1519 22.8457C27.1519 22.249 27.1519 21.9506 27.2766 21.784C27.3853 21.6388 27.5517 21.548 27.7325 21.5351C27.9401 21.5202 28.1911 21.6816 28.6931 22.0043L34.5957 25.7988C35.0313 26.0788 35.2491 26.2189 35.3243 26.3969C35.39 26.5525 35.39 26.728 35.3243 26.8836C35.2491 27.0616 35.0313 27.2016 34.5957 27.4817L28.6931 31.2762C28.1911 31.5989 27.9401 31.7602 27.7325 31.7454C27.5517 31.7325 27.3853 31.6417 27.2766 31.4965C27.1519 31.3299 27.1519 31.0315 27.1519 30.4347V22.8457Z' stroke='%235F6FFF' stroke-width='2.50076' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M16.6553 21.3886C16.6553 19.2878 16.6553 18.2374 17.0641 17.435C17.4238 16.7291 17.9976 16.1553 18.7034 15.7957C19.5058 15.3868 20.5563 15.3868 22.6571 15.3868L37.8986 15.3868C39.9994 15.3868 41.0498 15.3868 41.8523 15.7957C42.5581 16.1553 43.1319 16.7291 43.4916 17.435C43.9004 18.2374 43.9004 19.2878 43.9004 21.3886V31.8918C43.9004 33.9927 43.9004 35.0431 43.4916 35.8455C43.1319 36.5513 42.5581 37.1252 41.8523 37.4848C41.0498 37.8937 39.9994 37.8937 37.8986 37.8937H22.6571C20.5563 37.8937 19.5058 37.8937 18.7034 37.4848C17.9976 37.1252 17.4238 36.5513 17.0641 35.8455C16.6553 35.0431 16.6553 33.9927 16.6553 31.8918V21.3886Z' stroke='%235F6FFF' stroke-width='2.50076' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cpath d='M27.1519 22.8456C27.1519 22.2488 27.1519 21.9504 27.2766 21.7839C27.3853 21.6387 27.5516 21.5479 27.7325 21.5349C27.9401 21.5201 28.1911 21.6815 28.6931 22.0042L34.5956 25.7987C35.0312 26.0787 35.249 26.2187 35.3243 26.3968C35.39 26.5523 35.39 26.7279 35.3243 26.8834C35.249 27.0615 35.0312 27.2015 34.5956 27.4815L28.6931 31.276C28.1911 31.5988 27.9401 31.7601 27.7325 31.7453C27.5516 31.7324 27.3853 31.6415 27.2766 31.4964C27.1519 31.3298 27.1519 31.0314 27.1519 30.4346V22.8456Z' stroke='white' stroke-width='2.50076' stroke-linecap='round' stroke-linejoin='round'/%3E%3Ccircle cx='21.5908' cy='46.3831' r='2.36914' fill='white'/%3E%3Ccircle cx='38.9648' cy='46.3831' r='2.36914' fill='white'/%3E%3Ccircle cx='30.3062' cy='46.3831' r='2.36914' fill='white'/%3E%3Cdefs%3E%3CclipPath id='clip0_1146_27749'%3E%3Crect width='30.0091' height='30.0091' fill='white' transform='translate(15.2739 11.6358)'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)
' fill='%231A31FF'/%3E%3Cpath d='M33.0079 26.4509C33.4977 26.2876 33.7426 26.206 33.9055 26.2641C34.0472 26.3146 34.1587 26.4261 34.2092 26.5679C34.2673 26.7307 34.1857 26.9756 34.0224 27.4654L32.5311 31.9392C32.4846 32.0787 32.4614 32.1485 32.4218 32.2064C32.3867 32.2577 32.3424 32.302 32.2911 32.3371C32.2331 32.3767 32.1634 32.4 32.0239 32.4465L27.55 33.9378C27.0603 34.101 26.8154 34.1827 26.6525 34.1246C26.5108 34.074 26.3993 33.9625 26.3487 33.8208C26.2907 33.658 26.3723 33.4131 26.5356 32.9233L28.0268 28.4494C28.0733 28.3099 28.0966 28.2402 28.1362 28.1823C28.1713 28.131 28.2156 28.0866 28.2669 28.0516C28.3248 28.0119 28.3946 27.9887 28.5341 27.9422L33.0079 26.4509Z' fill='white' stroke='white' stroke-width='1.3534' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M30.2793 15.716C38.2752 15.7161 44.7568 22.1986 44.7568 30.1945C44.7567 38.1904 38.2752 44.6719 30.2793 44.6721C22.2833 44.6721 15.8009 38.1905 15.8008 30.1945C15.8008 22.1985 22.2833 15.716 30.2793 15.716ZM28.9629 19.6652V18.4211C26.6783 18.6736 24.5908 19.5775 22.8867 20.9406L23.7646 21.8185C24.2783 22.3326 24.2785 23.166 23.7646 23.6799C23.2508 24.1937 22.4174 24.1935 21.9033 23.6799L21.0254 22.8019C19.6623 24.5061 18.7584 26.5935 18.5059 28.8781H19.75C20.4767 28.8783 21.0654 29.4678 21.0654 30.1945C21.0653 30.9212 20.4766 31.5107 19.75 31.5109H18.5059C18.7585 33.7952 19.6625 35.8822 21.0254 37.5861L21.9033 36.7092C22.4173 36.1953 23.2507 36.1952 23.7646 36.7092C24.2784 37.2231 24.2784 38.0565 23.7646 38.5705L22.8867 39.4474C24.5908 40.8107 26.6782 41.7134 28.9629 41.966V40.7238C28.9629 39.9969 29.5524 39.4074 30.2793 39.4074C31.0061 39.4075 31.5957 39.997 31.5957 40.7238V41.966C33.8801 41.7134 35.9669 40.8104 37.6709 39.4474L36.7939 38.5705C36.2799 38.0565 36.2799 37.2232 36.7939 36.7092C37.3079 36.1952 38.1413 36.1952 38.6553 36.7092L39.5322 37.5861C40.8952 35.8821 41.7991 33.7953 42.0518 31.5109H40.8086C40.0818 31.5109 39.4923 30.9213 39.4922 30.1945C39.4922 29.4676 40.0817 28.8781 40.8086 28.8781H42.0518C41.7992 26.5934 40.8955 24.5061 39.5322 22.8019L38.6553 23.6799C38.1413 24.1936 37.3079 24.1936 36.7939 23.6799C36.28 23.1659 36.2801 22.3326 36.7939 21.8185L37.6709 20.9406C35.9669 19.5777 33.88 18.6737 31.5957 18.4211V19.6652C31.5955 20.3919 31.006 20.9805 30.2793 20.9807C29.5525 20.9807 28.9631 20.3919 28.9629 19.6652Z' fill='%235F6FFF'/%3E%3C/svg%3E)

' fill='%231A31FF'/%3E%3Cpath d='M148 32.5C149.657 32.5 151 33.8431 151 35.5V38.5H160C163.314 38.5 166 41.1863 166 44.5V104.5C166 107.814 163.314 110.5 160 110.5H100C96.6863 110.5 94 107.814 94 104.5V44.5C94 41.1863 96.6863 38.5 100 38.5H109V35.5C109 33.8431 110.343 32.5 112 32.5C113.657 32.5 115 33.8431 115 35.5V38.5H145V35.5C145 33.8431 146.343 32.5 148 32.5ZM100 62.5V104.5H160V62.5H100ZM100 56.5H160V44.5H151V47.5C151 49.1569 149.657 50.5 148 50.5C146.343 50.5 145 49.1569 145 47.5V44.5H115V47.5C115 49.1569 113.657 50.5 112 50.5C110.343 50.5 109 49.1569 109 47.5V44.5H100V56.5Z' fill='%235F6FFF'/%3E%3Cg clip-path='url(%23clip0_1146_28342)'%3E%3Cpath d='M130 80.5C132.485 80.5 134.5 78.4853 134.5 76C134.5 73.5147 132.485 71.5 130 71.5C127.515 71.5 125.5 73.5147 125.5 76C125.5 78.4853 127.515 80.5 130 80.5Z' fill='%235F6FFF'/%3E%3Cpath d='M146.5 80.5C148.985 80.5 151 78.4853 151 76C151 73.5147 148.985 71.5 146.5 71.5C144.015 71.5 142 73.5147 142 76C142 78.4853 144.015 80.5 146.5 80.5Z' fill='white'/%3E%3Cpath d='M113.5 95.5C115.985 95.5 118 93.4853 118 91C118 88.5147 115.985 86.5 113.5 86.5C111.015 86.5 109 88.5147 109 91C109 93.4853 111.015 95.5 113.5 95.5Z' fill='%235F6FFF'/%3E%3Cpath d='M130 95.5C132.485 95.5 134.5 93.4853 134.5 91C134.5 88.5147 132.485 86.5 130 86.5C127.515 86.5 125.5 88.5147 125.5 91C125.5 93.4853 127.515 95.5 130 95.5Z' fill='%235F6FFF'/%3E%3Cpath d='M146.5 95.5C148.985 95.5 151 93.4853 151 91C151 88.5147 148.985 86.5 146.5 86.5C144.015 86.5 142 88.5147 142 91C142 93.4853 144.015 95.5 146.5 95.5Z' fill='%235F6FFF'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_1146_28342'%3E%3Crect width='96' height='96' fill='white' transform='translate(82 26.5)'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)
' fill='%231A31FF'/%3E%3Cpath d='M120.215 63.2149L108.43 51.4298M108.43 98.5703L120.215 86.7851M143.785 86.7851L155.57 98.5701M155.57 51.4297L143.785 63.2148' stroke='white' stroke-width='6.66667' stroke-linejoin='round'/%3E%3Cpath d='M132 108.333C150.409 108.333 165.333 93.4095 165.333 75C165.333 56.5905 150.409 41.6666 132 41.6666C113.59 41.6666 98.6665 56.5905 98.6665 75C98.6665 93.4095 113.59 108.333 132 108.333Z' stroke='%235F6FFF' stroke-width='6.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M132 91.6666C141.205 91.6666 148.667 84.2047 148.667 75C148.667 65.7952 141.205 58.3333 132 58.3333C122.795 58.3333 115.333 65.7952 115.333 75C115.333 84.2047 122.795 91.6666 132 91.6666Z' stroke='%235F6FFF' stroke-width='6.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/svg%3E)
' fill='%231A31FF'/%3E%3Cpath d='M123.333 85L113.082 95.3789C111.652 96.8267 110.938 97.5505 110.323 97.6016C109.79 97.6459 109.268 97.4316 108.92 97.0254C108.518 96.5573 108.518 95.5399 108.518 93.5051V88.3053C108.518 86.4798 107.023 85.1589 105.217 84.8944C100.846 84.254 97.4124 80.8208 96.7721 76.4493C96.6665 75.7285 96.6665 74.8683 96.6665 73.1481V57.6666C96.6665 52.0661 96.6665 49.2658 97.7564 47.1267C98.7152 45.2451 100.245 43.7153 102.127 42.7566C104.266 41.6666 107.066 41.6666 112.667 41.6666H137.333C142.934 41.6666 145.734 41.6666 147.873 42.7566C149.755 43.7153 151.284 45.2451 152.243 47.1267C153.333 49.2658 153.333 52.0661 153.333 57.6666V71.6666M153.333 108.333L146.078 103.29C145.059 102.581 144.549 102.226 143.994 101.975C143.501 101.752 142.983 101.589 142.452 101.491C141.853 101.381 141.232 101.381 139.99 101.381H134C130.266 101.381 128.399 101.381 126.973 100.654C125.719 100.015 124.699 98.9953 124.06 97.7408C123.333 96.3148 123.333 94.4479 123.333 90.7142V82.3333C123.333 78.5996 123.333 76.7328 124.06 75.3067C124.699 74.0523 125.719 73.0324 126.973 72.3932C128.399 71.6666 130.266 71.6666 134 71.6666H152.667C156.4 71.6666 158.267 71.6666 159.693 72.3932C160.948 73.0324 161.967 74.0523 162.607 75.3067C163.333 76.7328 163.333 78.5996 163.333 82.3333V91.3809C163.333 94.4872 163.333 96.0403 162.826 97.2655C162.149 98.899 160.851 100.197 159.218 100.873C157.993 101.381 156.439 101.381 153.333 101.381V108.333Z' stroke='%235F6FFF' stroke-width='6.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M163.333 82.3333C163.333 78.5996 163.333 76.7328 162.607 75.3067C161.968 74.0523 160.948 73.0324 159.693 72.3932C158.267 71.6666 156.401 71.6666 152.667 71.6666H134C130.266 71.6666 128.4 71.6666 126.974 72.3932C125.719 73.0324 124.699 74.0523 124.06 75.3067C123.333 76.7328 123.333 78.5996 123.333 82.3333V90.7142C123.333 94.4479 123.333 96.3148 124.06 97.7408C124.699 98.9953 125.719 100.015 126.974 100.654C128.4 101.381 130.266 101.381 134 101.381H139.99C141.232 101.381 141.853 101.381 142.452 101.491C142.984 101.589 143.502 101.752 143.994 101.975C144.549 102.226 145.059 102.581 146.079 103.29L153.333 108.333V101.381C156.44 101.381 157.993 101.381 159.218 100.873C160.852 100.197 162.149 98.899 162.826 97.2655C163.333 96.0403 163.333 94.4872 163.333 91.3809V82.3333Z' stroke='white' stroke-width='6.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/svg%3E)
' fill='%231A31FF'/%3E%3Cpath d='M149.167 84.5834V73.062C149.167 72.374 149.167 72.03 149.062 71.7263C148.969 71.4577 148.818 71.2131 148.619 71.0101C148.394 70.7806 148.087 70.6268 147.471 70.3191L130 61.5834M99.3332 65.4167V91.5087C99.3332 92.9344 99.3332 93.6472 99.5556 94.2714C99.7522 94.8231 100.073 95.3225 100.492 95.7311C100.967 96.1933 101.615 96.4903 102.911 97.0843L127.444 108.329C128.384 108.76 128.854 108.975 129.344 109.06C129.778 109.135 130.222 109.135 130.656 109.06C131.145 108.975 131.615 108.76 132.555 108.329L157.089 97.0843C158.385 96.4903 159.033 96.1933 159.507 95.7311C159.927 95.3225 160.247 94.8231 160.444 94.2714C160.667 93.6472 160.667 92.9344 160.667 91.5087V65.4167M91.6665 61.5834L128.628 43.1024C129.131 42.851 129.383 42.7253 129.646 42.6758C129.88 42.632 130.12 42.632 130.353 42.6758C130.617 42.7253 130.868 42.851 131.371 43.1024L168.333 61.5834L131.371 80.0643C130.868 80.3157 130.617 80.4415 130.353 80.4909C130.12 80.5348 129.88 80.5348 129.646 80.4909C129.383 80.4415 129.131 80.3157 128.628 80.0643L91.6665 61.5834Z' stroke='%235F6FFF' stroke-width='7.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3Cpath d='M149.167 84.5834V73.062C149.167 72.374 149.167 72.03 149.062 71.7263C148.969 71.4577 148.818 71.2131 148.619 71.0101C148.395 70.7806 148.087 70.6268 147.471 70.3191L130 61.5834' stroke='white' stroke-width='7.66667' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/svg%3E)
'%3E%3Cg clip-path='url(%23clip1_735_18784)'%3E%3Cpath d='M35.8438 9.53125V31.4688H24.875C23.5821 31.4688 22.3421 31.9824 21.4279 32.8966C20.5136 33.8108 20 35.0508 20 36.3438V14.4062C20 13.1133 20.5136 11.8733 21.4279 10.9591C22.3421 10.0449 23.5821 9.53125 24.875 9.53125H35.8438Z' fill='%23E8FF26'/%3E%3Cpath d='M35.8438 8.3125H24.875C23.929 8.3125 22.9959 8.53276 22.1498 8.95583C21.3036 9.37891 20.5676 9.99318 20 10.75C19.4324 9.99318 18.6964 9.37891 17.8502 8.95583C17.0041 8.53276 16.071 8.3125 15.125 8.3125H4.15625C3.83302 8.3125 3.52302 8.4409 3.29446 8.66946C3.0659 8.89802 2.9375 9.20802 2.9375 9.53125V31.4688C2.9375 31.792 3.0659 32.102 3.29446 32.3305C3.52302 32.5591 3.83302 32.6875 4.15625 32.6875H15.125C16.0947 32.6875 17.0247 33.0727 17.7104 33.7584C18.396 34.4441 18.7812 35.3741 18.7812 36.3438C18.7812 36.667 18.9097 36.977 19.1382 37.2055C19.3668 37.4341 19.6768 37.5625 20 37.5625C20.3232 37.5625 20.6332 37.4341 20.8618 37.2055C21.0903 36.977 21.2188 36.667 21.2188 36.3438C21.2188 35.3741 21.604 34.4441 22.2896 33.7584C22.9753 33.0727 23.9053 32.6875 24.875 32.6875H35.8438C36.167 32.6875 36.477 32.5591 36.7055 32.3305C36.9341 32.102 37.0625 31.792 37.0625 31.4688V9.53125C37.0625 9.20802 36.9341 8.89802 36.7055 8.66946C36.477 8.4409 36.167 8.3125 35.8438 8.3125ZM15.125 30.25H5.375V10.75H15.125C16.0947 10.75 17.0247 11.1352 17.7104 11.8209C18.396 12.5066 18.7812 13.4366 18.7812 14.4062V31.4688C17.7274 30.6758 16.4438 30.2479 15.125 30.25ZM34.625 30.25H24.875C23.5562 30.2479 22.2726 30.6758 21.2188 31.4688V14.4062C21.2188 13.4366 21.604 12.5066 22.2896 11.8209C22.9753 11.1352 23.9053 10.75 24.875 10.75H34.625V30.25ZM24.875 14.4062H30.9688C31.292 14.4062 31.602 14.5347 31.8305 14.7632C32.0591 14.9918 32.1875 15.3018 32.1875 15.625C32.1875 15.9482 32.0591 16.2582 31.8305 16.4868C31.602 16.7153 31.292 16.8438 30.9688 16.8438H24.875C24.5518 16.8438 24.2418 16.7153 24.0132 16.4868C23.7847 16.2582 23.6562 15.9482 23.6562 15.625C23.6562 15.3018 23.7847 14.9918 24.0132 14.7632C24.2418 14.5347 24.5518 14.4062 24.875 14.4062ZM32.1875 20.5C32.1875 20.8232 32.0591 21.1332 31.8305 21.3618C31.602 21.5903 31.292 21.7188 30.9688 21.7188H24.875C24.5518 21.7188 24.2418 21.5903 24.0132 21.3618C23.7847 21.1332 23.6562 20.8232 23.6562 20.5C23.6562 20.1768 23.7847 19.8668 24.0132 19.6382C24.2418 19.4097 24.5518 19.2812 24.875 19.2812H30.9688C31.292 19.2812 31.602 19.4097 31.8305 19.6382C32.0591 19.8668 32.1875 20.1768 32.1875 20.5ZM32.1875 25.375C32.1875 25.6982 32.0591 26.0082 31.8305 26.2368C31.602 26.4653 31.292 26.5938 30.9688 26.5938H24.875C24.5518 26.5938 24.2418 26.4653 24.0132 26.2368C23.7847 26.0082 23.6562 25.6982 23.6562 25.375C23.6562 25.0518 23.7847 24.7418 24.0132 24.5132C24.2418 24.2847 24.5518 24.1562 24.875 24.1562H30.9688C31.292 24.1562 31.602 24.2847 31.8305 24.5132C32.0591 24.7418 32.1875 25.0518 32.1875 25.375Z' fill='%231A31FF'/%3E%3C/g%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_735_18784'%3E%3Crect width='40' height='40' rx='2' fill='white'/%3E%3C/clipPath%3E%3CclipPath id='clip1_735_18784'%3E%3Crect width='39' height='39' fill='white' transform='translate(0.5 1)'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)

'%3E%3Cpath d='M3.98722 14.5788C4.44347 13.5039 5.50869 12.75 6.75 12.75H11.25C12.4913 12.75 13.5565 13.5039 14.0128 14.5788M12 7.125C12 8.78185 10.6569 10.125 9 10.125C7.34315 10.125 6 8.78185 6 7.125C6 5.46815 7.34315 4.125 9 4.125C10.6569 4.125 12 5.46815 12 7.125ZM16.5 9C16.5 13.1421 13.1421 16.5 9 16.5C4.85786 16.5 1.5 13.1421 1.5 9C1.5 4.85786 4.85786 1.5 9 1.5C13.1421 1.5 16.5 4.85786 16.5 9Z' stroke='%231A31FF' stroke-width='1.25' stroke-linecap='round' stroke-linejoin='round'/%3E%3C/g%3E%3Cdefs%3E%3CclipPath id='clip0_220_713'%3E%3Crect width='18' height='18' fill='white'/%3E%3C/clipPath%3E%3C/defs%3E%3C/svg%3E)


The quick download:
Network analysis tools earn their keep when they solve your real operational problems and plug into your workflows.
-
Organizations that define clear performance objectives before evaluating tools avoid the “vanity metrics” trap and focus monitoring on the dependencies that matter most: DNS, BGP, ISPs, and CDNs.
-
A blended approach combining synthetic monitoring with real-user monitoring (RUM) closes the gap between predicting problems and measuring their actual impact on users.
-
Tools that translate telemetry into prioritized, actionable insights, including fault isolation, blast radius, and recommended next steps, cut mean time to resolve (MTTR) significantly.
-
Choose a tool that proves itself in a real proof of concept on your network, not a polished demo, and validates integration with your ITSM and SIEM workflows before you commit.
Effective network operations require deep visibility into traffic behavior, performance metrics, and protocol interactions across the entire infrastructure. Network analysis tools provide this visibility by capturing, inspecting, and correlating packet flows, device telemetry, and application data, both historically and in real time.
Network analysis tools ingest a wide variety of telemetry and monitoring data of different types, formats, and sources. Organizations collect, process, correlate, store, and utilize the data to observe the state of the network and its services in detail.
The result is a deep observability that aids in alerting and troubleshooting by providing preliminary diagnoses to network operators. Administrators can identify latency, packet loss, routing anomalies, and security threats, validate configurations, and optimize performance under varying loads. Network analysis tools are part of the foundation for capacity planning, policy verification, and long-term performance baselining.
Modern networks continue to grow in scale and complexity. They often span hybrid cloud environments, SD-WAN, IoT, and edge architectures. As a result, the ability to select and integrate the right network analysis tool is now critical to maintaining reliability, security, and operational efficiency.
This article examines network analysis tools, how they aid network administrators in their duties, and the best practices for selecting and using them. It demonstrates how real-time end-to-end visibility across the Internet stack can transform raw telemetry into actionable insights, enabling improvements in performance, user experience, and security in hybrid and multi-cloud environments.
Summary of Network Analysis Tool Best Practices and Recommendations
| Best practice | Description |
|---|---|
| Define clear objectives | Identify performance goals and troubleshooting needs before evaluating tools. |
| Prioritize real-time visibility | Choose a tool that delivers immediate insights to quickly detect and resolve issues. |
| Evaluate data collection methods | Understand the differences between active and passive monitoring, and determine whether one, the other, or both are best suited for your network’s needs. |
| Verify integration and scalability | Ensure the tool integrates with existing systems and can grow organically with your system. |
| Focus on actionable insights | Select and employ a tool that translates data into clear, prioritized recommendations. |
| Test before committing | Run proof-of-concept trials to validate the tool’s accuracy, usability, and performance. |
Establishing the proper network analysis tools from the beginning, based on your requirements, is an important best practice in itself.
Define Clear Objectives: Knowing What You Want
To get the most out of your network analysis tools, you need to become intimately familiar with your requirements. What objectives do you have, and what are the specific needs of your network? Start with the most important customer interactions and the dependencies that can break them, such as DNS, BGP routing, ISP paths, CDN, etc. Then you can translate those into measurable goals that link to the information the tool must provide.
Questions you should ask vendors:
- How do you separate internal network faults from those that come from third-party services?
- Can you correlate synthetic findings with real-user impact (RUM) and historical patterns?
Common pitfalls to avoid:
- Don’t fall into the trap of letting a tool’s feature set define your goals. It should be the other way around.
- Don’t focus on “vanity metrics” such as average latency across all users. Such metrics may not raise alerts even if peak times in certain regions surpass thresholds.
- Don’t ignore dependencies on external services.
Prioritize Real-Time Visibility
Real-time (or near real-time) visibility minimizes mean time to detect (MTTD) and mean time to resolve (MTTR) thresholds, which can significantly improve network response metrics. This is especially useful when the source of the problem detected is outside of your network.
To achieve meaningful visibility, it’s important to set specific detection threshold targets and acquire distributed vantage points, including last-mile, enterprise, and backbone nodes.
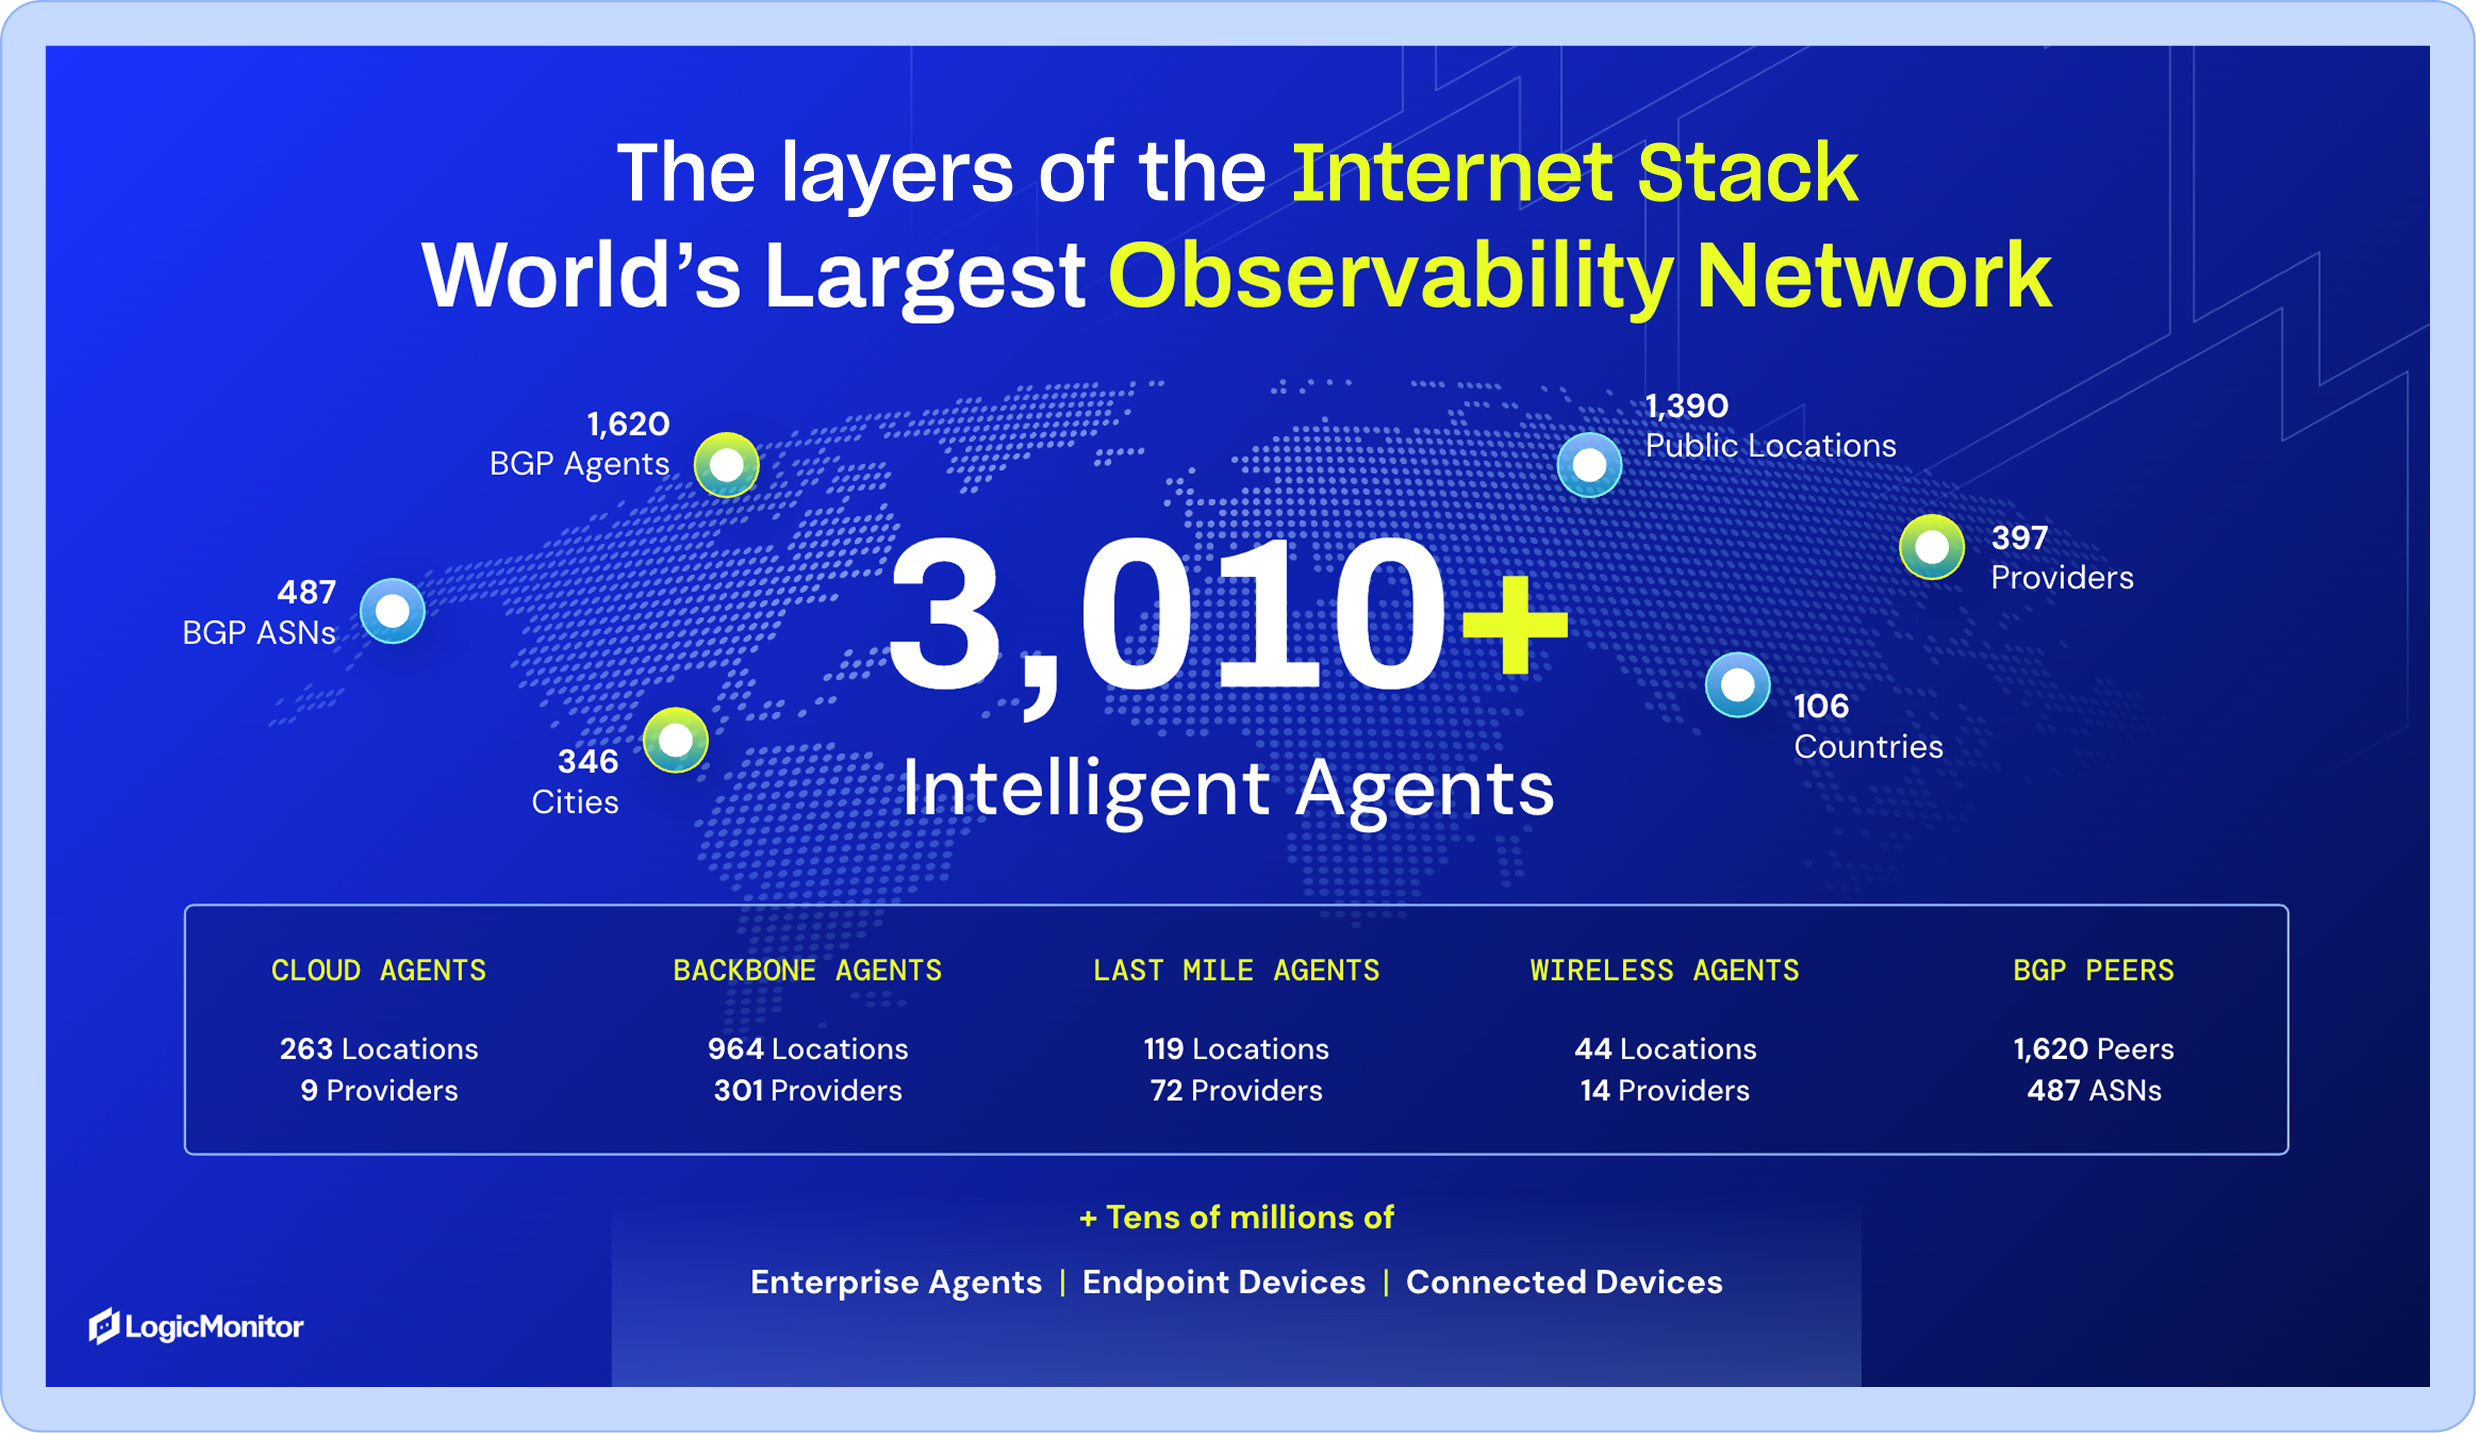
LogicMonitor’s global agent network delivers visibility across last-mile, enterprise, and backbone nodes
Questions you should ask vendors:
- What’s the typical time interval from event to alert for synthetic and RUM monitoring?
- Can network regions, and even devices themselves, be logically segmented to understand blast radius in real time?
- Do alerts include layer/provider information and first remediation steps out of the box?
Common pitfalls to avoid:
- Don’t rely on batch RUM telemetry only, as you’ll learn about an outage too late.
- Single-vantage-point solutions can overlook last-mile and ISP issues.
- Lack of dependency tests results in incidents that are poorly diagnosed.
Evaluate Data Collection Methods
Network analysis tool response times depend upon the method through which data is collected.
Active monitoring involves scripted checks from multiple vantage points that proactively test and detect problems before they impact end users.
Passive monitoring observes real traffic and detects actual impact on the network and its users. This can include RUM, packet captures, device telemetries, and network traffic flow and metadata.
A blended strategy addresses both sides of the problem: predicting issues before they hit users and measuring their actual impact when they do.
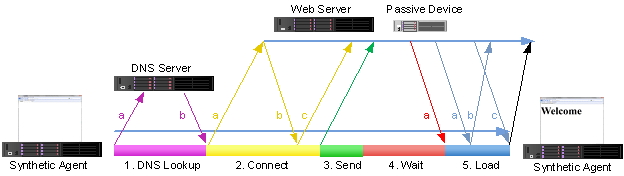
An example of how active (synthetic) monitoring can span multiple network components and services
Using a blended approach allows network administrators to be both proactive (through synthetic monitoring) and confident in the information they receive, helping them accurately identify who was affected and why.
Questions you should ask vendors:
- How do you correlate synthetic findings with RUM results to show both symptom and impact?
- Can you monitor DNS, BGP, CDN, SaaS, and APIs and attribute incidents to the correct layer and provider?
Relying on a single method (synthetic OR RUM) can leave you blind to either potential issues or actual impact.
Verify Integration and Scalability
Your network analysis tool must function as part of a broader network monitoring strategy and interact with other systems in the existing ecosystem. The tool must also adapt and grow in accordance with future traffic patterns and the evolution of your network.
Integration involves interaction with ITSMs, forwarding events and metrics to SIEMs, and processing cloud flow logs and telemetry. Scalability means that vantage points should be added without requiring redesign, data pipelines should have headroom to sustain event spikes without lag or loss, and alert delivery should be guaranteed.
Questions you should ask vendors:
- For ITSM, what fields are populated, and can tickets be updated and closed automatically?
- Is near-real-time data streaming and bulk export supported for data egress?
Common pitfalls to avoid:
- Choosing a solution that’s ideal for today, but is difficult to modify or scale.
- Opting for a more “closed” solution makes it difficult to integrate with a wide variety of other tools in the ecosystem.
Focus on Actionable Insights
Network analysis tools should present data in a form that allows you to formulate a meaningful response. Actionable insights provide the necessary context to inform decisions, enabling you to act with confidence. For example, the network analysis tool should provide:
- Clear priority cues.
- Incident ranking based on business impact instead of a long list of uncategorized chronological events.
- Fast fault hints, along with an indication of the blast radius at a glance.
- Suggested next steps, including recommended tests and a one-click traceability option.
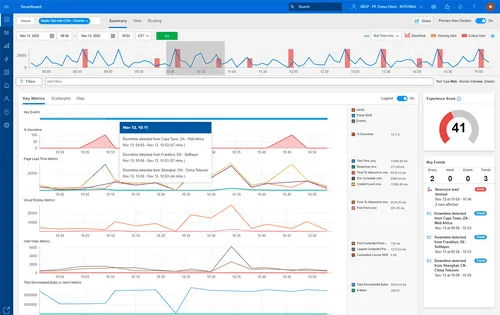
An example of a dashboard that gives meaningful data about the network, which provides actionable insights.
Providing network techs with contextual information saves the minutes they’d otherwise spend hunting through raw data.
Questions you should ask vendors:
- Examples of incident cards that include the actionable insights and information typically found in a typical alert.
- How customizable is the information included in alerts, and how many variations can be configured for different teams without needing to rebuild dashboards?
Avoid focusing on dashboard aesthetics at the expense of the value of the information presented.
Test Before Committing
Before committing to a particular network analysis tool, thoroughly test it in a real-world scenario. A proof of concept should mimic your real network conditions, and it shouldn’t be a simple polished demo. The aim is to prove that the tool can spot problems on your network quickly, pinpoint the root cause, and integrate well with your workflows.
Questions you should ask vendors:
- Can we run the proof of concept on our incidents and observe the detection, diagnosis, and action timeline?
- Will the proof of concept include integrating all other entities within our network ecosystem, such as ITSM and SIEM?
Common pitfalls to avoid:
- Evaluating network analysis tools based only on demos.
- Testing integrations in the trial.
Deeper Context for Specific Use Cases
The end-to-end set of dependencies that deliver a digital experience spans multiple protocols and services, including DNS, BGP, ISPs, CDNs, SaaS, cloud services, and individual apps. A network analysis tool must see across the entire Internet stack, correlate signals, and recommend the next appropriate action.
LogicMonitor Internet Performance Monitoring blends synthetic monitoring with RUM, DNS, and BGP tests, API/CDN checks, and endpoint digital experience monitoring. All monitoring is performed by intelligent agents across last-mile, enterprise, and backbone networks. Its stack map turns noisy telemetry into focused guidance.
The following sections describe various use cases and illustrate how Internet Performance Monitoring helps address them.
Identify the Root Cause of Performance Degradation
You’re informed of checkout slowdowns in the EU region. Synthetics show that application source servers are functioning correctly, but DNS resolution times are elevated in one provider region. Internet Stack Map attributes the fault to DNS, while RUM confirms the impact for specific ASNs.
You switch DNS resolvers and notify the vendor. MTTR drops, and customer transactions recover.
Troubleshoot Latency, Packet Loss, and Jitter
Remote users report choppy video. Distributed probes from residential ISPs isolate packet loss on a transit segment, while endpoint agents rule out home Wi-Fi problems.
IPM attributes the issue to a named provider path and quantifies the blast radius by region and ASN.
Optimize Application Delivery
South American regions show poor time to first byte (TTFB). CDN object tests reveal suboptimal server (edge) selection, while RUM trends pinpoint when and where it’s the worst. You adjust CDN policies to reduce latency and improve Core Web Vitals.
Detect Abnormal Traffic Patterns for Security Insight
API errors spike from a narrow set of networks. Synthetic checks and traffic indicators flag the anomaly. RUM shows a contained impact.
IPM indicates offending ASNs and recommends throttling or geofencing. You rate-limit, watch errors normalize, and preserve an audit trail.
Last Thoughts
Network analysis tools turn complex, multi-cloud delivery chains into clear, timely decisions that protect performance, user experience, and security. Define objectives, insist on real-time visibility, focus on actionable insights, and prove it all in a proof of concept.
Above all, choose the tool that isolates faults across owned and third-party networks and fits your workflows. The right tool shortens the distance from “something’s wrong” to “here’s where it broke and what to do next.”
The end goal of any network analysis tool is knowing what’s failing, where, and why. LogicMonitor helps you achieve that control with continuous monitoring, fault isolation, and actionable insights built for distributed systems.
Take control of your network visibility from edge to cloud.
Get continuous monitoring, fault isolation, and actionable insights across your entire hybrid infrastructure with LogicMonitor.
FAQs
What’s the difference between active and passive network monitoring?
Active monitoring uses scripted checks from distributed vantage points to proactively test network components before users are affected. Passive monitoring observes real traffic, including RUM, packet captures, and flow data, to measure actual user impact. A blended approach combining both gives you predictive detection and confirmed impact measurement.
How do network analysis tools reduce mean time to resolve (MTTR)?
They correlate telemetry from multiple sources (synthetic tests, RUM, DNS, BGP) and attribute faults to specific layers, providers, or network segments. Instead of manually sifting through raw data, operators get prioritized incident cards with blast radius, root cause hints, and recommended next steps.
What should I look for when running a proof of concept for a network analysis tool?
Run the POC against your real network conditions and actual incidents, not a vendor-prepared demo environment. Validate detection speed, diagnostic accuracy, integration with your ITSM and SIEM platforms, and whether the tool’s alert workflows match how your team operates.
How do I avoid selecting a network analysis tool based on features I don’t need?
Start by defining your operational objectives and the specific dependencies that affect your users (DNS, BGP, ISP paths, CDN). Map those to measurable goals, then evaluate tools against those goals. Let your requirements drive the selection, not the vendor’s feature list.